Morgan Coleman · 14 September 2026
Examining Crawl Budget Allocation in High-Volume Industry Portals
Crawl budget represents the volume of pages search engine bots can and will process on a website during a specific period, and high-volume industry portals such as job boards, real estate directories, and e-commerce marketplaces often face complex allocation challenges because of their scale and update frequency. Researchers have documented that these sites generate thousands of new or revised pages daily, which means allocation decisions directly influence how quickly content reaches search indexes and how comprehensively bots discover updates.
Core Mechanics of Crawl Budget Distribution
Search engines calculate crawl budget through a combination of host load capacity, historical crawl demand, and site popularity signals, while factors like server response codes, page load speed, and internal link structures further shape daily limits. Data from industry reports shows that portals exceeding one million indexed pages frequently experience uneven distribution where certain sections receive priority over others based on perceived value and freshness. Observers note that bots prioritize URLs with strong signals such as recent changes or high inbound links, whereas duplicate or low-traffic pages often receive reduced attention.
High-volume portals typically maintain sitemaps that list millions of URLs, yet bots rarely process every entry in a single visit, and this selective behavior stems from algorithmic evaluations of content quality and duplication rates. Studies conducted by academic institutions have measured that sites with optimized XML sitemaps see up to 30 percent more efficient processing when compared to those relying solely on internal navigation, because structured files help bots identify priority paths without excessive trial and error.
Technical Factors Influencing Allocation in Large Portals
Server performance plays a central role, since slow response times or frequent 5xx errors signal reduced capacity to bots and trigger automatic throttling. Industry portals often deploy content delivery networks and edge caching to maintain sub-second load speeds across geographic regions, and these infrastructure choices allow greater daily crawl volumes according to metrics tracked in web performance databases. Additionally, robots.txt directives and meta tags such as noindex or canonical links guide allocation by preventing bots from wasting resources on low-value sections like filtered search results or user-generated archives.
Internal linking architecture further determines distribution patterns, because well-connected page clusters receive more frequent visits while orphaned content falls outside regular routes. Those who manage high-volume sites have observed that implementing hub-and-spoke link models, where category pages connect to deep content, improves coverage rates without increasing overall requests. Data indicates that portals updating millions of listings weekly benefit from dynamic sitemap generation that reflects real-time changes rather than static files refreshed monthly.
Patterns Observed in Industry-Specific Environments
Job portals and real estate platforms illustrate distinct allocation behaviors because their content changes rapidly with new postings and listings, and search engines respond by allocating higher budgets during peak update periods. A Canadian digital economy study found that sites refreshing over 50,000 pages per day achieved better indexation when they segmented sitemaps by content type and submission date, allowing bots to focus on active sections first. Similarly, European trade analyses have shown that portals using structured data markup experience accelerated processing since schema helps classify content relevance without additional crawling overhead.
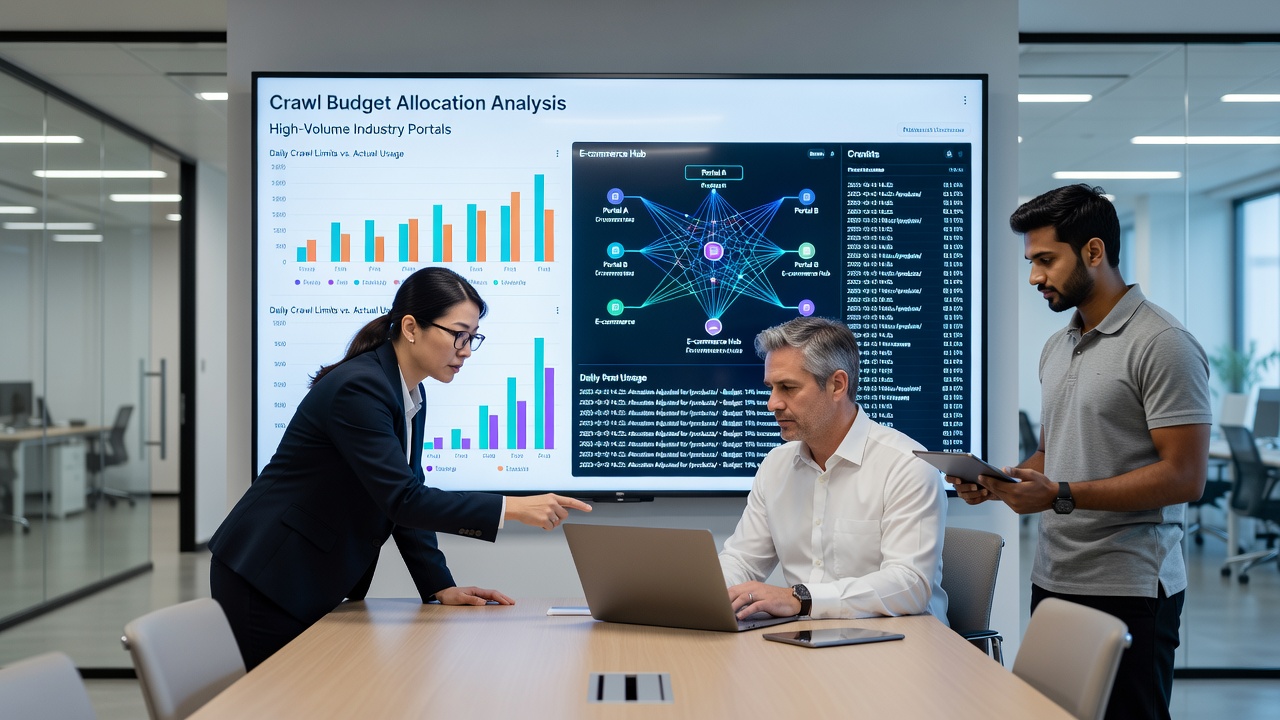
September 2026 brought continued refinements to how major engines handle large-scale dynamic sites, with emphasis on sustainability metrics such as energy-efficient crawling schedules that align with server availability windows. Portals in sectors like automotive classifieds and travel aggregators have adopted log-file analysis tools to track actual versus requested crawl volumes, revealing gaps where certain subdomains receive under-allocation despite high user engagement.
Measurement Approaches and Data Sources
Log file analysis remains the primary method for understanding allocation realities, since server records capture every bot request alongside status codes and response times. Those responsible for portal maintenance combine these logs with search console data to identify under-crawled sections and adjust internal signals accordingly. Research from Australian academic centers has quantified that portals incorporating crawl-delay parameters in robots.txt achieve more stable allocation during traffic spikes, preventing temporary overloads that reduce future visits.
External benchmarks from organizations such as the Internet Corporation for Assigned Names and Numbers provide context on domain-level health indicators that indirectly affect crawl priority, while reports issued by the European Commission on digital infrastructure track how regulatory frameworks influence data handling practices that bots evaluate during visits.
Conclusion
Effective crawl budget allocation in high-volume industry portals depends on coordinated technical optimizations that align server capacity, content structure, and signaling mechanisms with engine requirements. Ongoing monitoring through logs and performance metrics allows administrators to identify inefficiencies and implement targeted adjustments that improve coverage without unnecessary resource expenditure. As portal architectures continue evolving alongside search engine capabilities, the relationship between site scale and allocation efficiency remains a measurable aspect of technical operations.